Related Topics:
Creating Rest Proxy Openai-
AI Technology Applied to Servers
AI servers are specialized systems using powerful GPUs for the intensive, parallel processing of AI models. Enterprises are investing billions of dollars in cloud. Related: Dell, HPE, and Others Unveil AI Innovations at GTC 2026 IDC reports the global server market reached a record $444 billion in 2025. With AI infrastructure remaining a strategic priority, IDC projects AI infrastructure spending will reach $487 billion in 2026 and surpass $1 trillion by. As AI accelerates from research labs to everyday operations, its footprint now spans cloud-scale training, on-premises systems, and billions of connected devices. Yet most AI services still assume a stable network path to distant data centers. These servers feature high-speed interconnects and large, fast. AI, or artificial intelligence, is changing the way organizations and businesses handle data by incorporating automation of complex calculations, introducing new advanced applications, and fulfilling computational demands like never before.
[PDF Version]
-
What to do if there is a problem with the AI Link server
This guide provides a structured approach to troubleshooting network link failures in AI data centers, specifically targeting issues where the link cannot up. "Is It Down Right Now" monitors the status of your favorite web sites and checks whether they are down or not. Just enter the url and a fresh site status test will be performed on the domain name in real time using our online website. Unable to access your agents Public access is disabled in the AI Service. Please open and configure a private endpoint connection. Learn more I've also tried to setup the Azure AIHub where the project is deployed by enabling the managed virtual network option and creating a private endpoint for the. Find out if a service is down in seconds. com" or "Gemini". Our system instantly pings the service from multiple global locations to verify its status. Get a clear 'Up' or 'Down' status in real-time. ” or “Hmm, something isn't right.
[PDF Version]
-
AI Server Delineation
AI servers are high-performance computing systems designed to process complex artificial intelligence workloads, including large-scale model training and real-time inference. This is where AI server clusters stand out, crafted for. Building and setting up your very own high-performance local AI server offers a fantastic solution to this. Indeed, the AI server market was valued at $38. 3 billion in 2023 and is estimated by Global Market. to design-center-comments@juniper. In this document, we explore the network infrastructure requirements of AI.
-
Power Consumption of an 8-GPU AI Server
Modern AI GPUs consume 700W-1,100W each. An 8-GPU server can draw 10kW or more, creating facility challenges that traditional IT infrastructure never faced. Accurate planning prevents budget overruns and identifies. Most teams budgeting for AI inference focus on one number: the GPU hourly rate. It is clean, predictable, and easy to model. The electricity bill does not show up until the first month of on-premise or colocation operations, and by then the budget is already set. Data centres are facilities used to house servers, storage systems, networking equipment and associated components that are installed in racks and organised into rows. Today, a single NVIDIA GB200 NVL72 AI rack draws 132 kW — more than 16 times as much. Google's latest-generation TPU, Ironwood, is claimed to be 30× more energy-efficient than its first publicly available TPU.
[PDF Version]
-
Memory in AI Servers
This guide provides a practical, data-driven framework to determine RAM requirements for AI workloads, including AI server memory planning, GPU RAM requirements, and large-scale LLM infrastructure design. AI workloads differ fundamentally from traditional enterprise. As a trusted U. Micron Technology has announced the sampling of its new 256-GB DDR5 registered dual in-line memory module (RDIMM) to key server ecosystem partners, targeting next-generation AI and. Local AI inference means running an already trained model on your own server. The model is not trained from scratch; it is used to answer questions, analyze documents, generate text, recognize speech, classify tickets, search a knowledge base or process images. SK Hynix officially begins mass production of its 192GB SOCAM M2 memory, “establishing a new benchmark for memory performance for AI servers. We will explore their architectural differences, their respective strengths and weaknesses in handling various AI tasks, and how to optimally configure them.
[PDF Version]
-
Network Gateway Core Switch
Includes dual power supplies, hot-swappable modules, link aggregation (LAG), and support for HSRP/VRRP. Modular chassis or stackable designs make it easy to scale as your network grows. Engineered to aggregate massive volumes of data from distribution switches, it provides ultra-low latency and maximum throughput to ensure uninterrupted routing and packet. The hierarchy Ethernet network is a three-layer integrated setup of networking devices. These networks are designed with three tiers that facilitate strategic installation, management, and maintenance, and so on. 0/24 you assign an SVI to every layer-2 switch and give it an IP in this range and the gateway for all the SVIs should be on the core (172. 1/24 example: access switch-1 172. 13/24. Network planning 1: The AR router accesses the Internet through DHCP or PPPoE on the WAN interface or the static IP address allocated by the carrier.
[PDF Version]
-
AI computing server price
Standard 3–5 year plans typically range from $15,000 to $40,000 per server, covering firmware, diagnostics, and parts replacement. Vendors like Supermicro offer flexible, OpEx-friendly options to help manage these expenses. AI servers, such as the HPE XD685 and Dell XE9680, equipped with eight NVIDIA H100 or H200 GPUs, consume over 7 kW per node, surpassing the 200–400 W baseline of traditional servers. This seismic shift in power demand transforms the economics of AI infrastructure. The cost of an AI server data. The AI data center market is valued at USD 344. 52 billion by 2032, growing at a CAGR of 27. Growth is driven by rising adoption of generative AI, machine learning, and large language models across industries, as well. AI implementation costs range from $5,000 for pilots to $500K+ for enterprise systems. Every layer of the stack, including GPU modules, memory, networking, power, and cooling, has repriced sharply heading into 2026.
[PDF Version]
-
Brunei AI Server Distributor
Find AI service providers, builders, trainers, and project teams in Brunei. WhatsApp automation and customer-service AI for. AI servers accelerate model training and real-time inference, delivering powerful computing with CPUs, GPUs, and specialized AI accelerators. Their scalable and efficient architecture enables businesses to run AI workloads faster and more effectively. AI servers provide powerful compute for. TRADETECH SDN BHD is a Brunei-based IT solutions provider delivering end-to-end technology supply, installation, and support services since 2007. Continuously delivering innovative ICT solutions that drive organizational success across government, education, and enterprise sectors.
-
Actual AI computing server
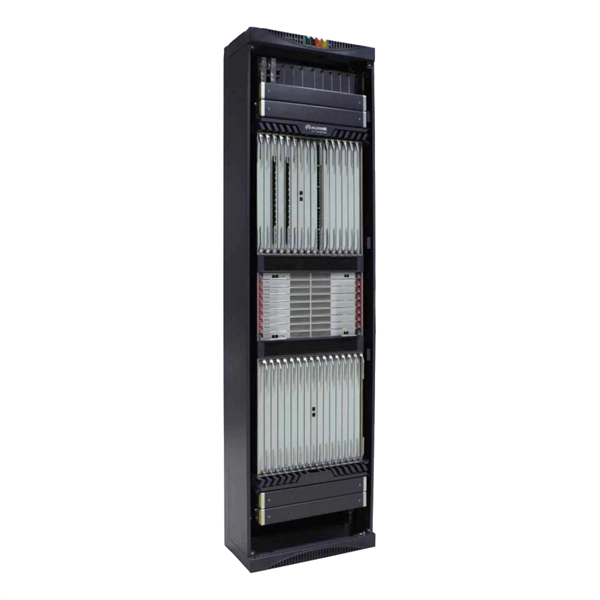
AI servers are high-performance computing systems designed to process complex artificial intelligence workloads, including large-scale model training and real-time inference. An AI server's architecture is all about. Altos offers a range of powerful and flexible AI server solution, designed to meet the demands of high-performance computing. They provide the hardware environment —. AI, or artificial intelligence, is changing the way organizations and businesses handle data by incorporating automation of complex calculations, introducing new advanced applications, and fulfilling computational demands like never before. Yet hardware is just one piece of the puzzle. Operating at low power usage.
-
Two fiber optic cables are connected to the back of the switch
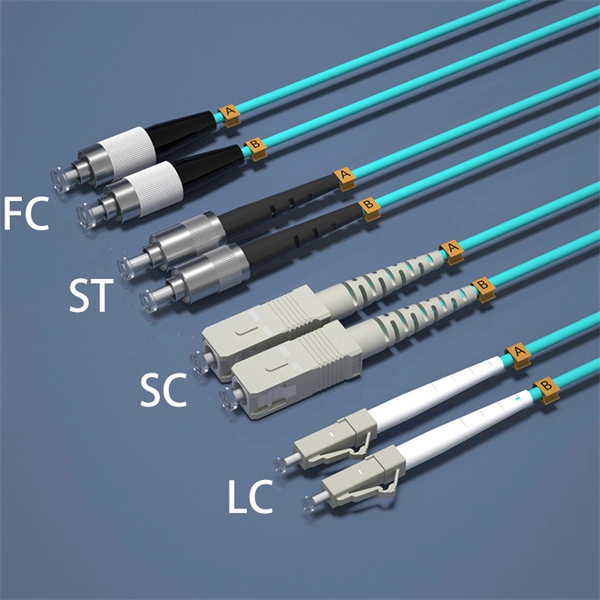
Choose an SFP module based on the fiber optic cabling that will be connected to the network switches. In addition, fiber cables can transmit data over several kilometers without signal degradation, making them ideal for connecting switches in large campus networks and between different buildings. As they do not emit electromagnetic signals, they're difficult to tap and secure against eavesdropping. I need to connect 4 Floor Building with 4 Cisco 2960 - 48 ports switch each other and it needs to be through a fiber. Can two switches with optical ports be directly connected by optical fiber? Yes, the main line of the optical fiber LAN is a direct. SFP transceiver modules are specific to the type of fiber being connected (either single mode or multimode). Always. In this video, we'll delve into the world of fiber optics, exploring the reasons behind their necessity, introducing Fiber Switches and Fiber PoE Switches, guiding you through the selection of the right fiber optic cables, and demonstrating the physical connection process.
[PDF Version]
-
Calculation of AI Server Heat Output
Heat Output = 700W × 0. 412 = 2,377 BTU/hr per GPU GPU heat alone = 8 × 2,377 = 19,016 BTU/hr Total server heat (with CPU, memory, networking): ASHRAE TC 9. 9 publishes the industry-standard thermal guidelines for data processing. A component's Thermal Design Power (TDP) is a good starting point for this calculation. To calculate your server's. Modern AI accelerators have dramatically increasing power requirements, with TDPs rising from 300W (V100) to over 1,400W (MI355X) Heat Output = 700W × 0. 1 Calculate Heat Load The total heat load is based on the power consumption of the servers and associated equipment. A single server rack packed with the latest NVIDIA GPUs can now consume over 100,000 watts of power—equivalent to the air conditioning load of 30 homes running simultaneously. Trying to cool. In contrast, AI data centers are optimized for high-performance computing (HPC) tasks: training machine learning models and running inference on large datasets using specialized accelerators (GPUs, TPUs, FPGAs, etc.
[PDF Version]